The Roadmap to Mastering LLM Inference Optimization: Essential Strategies and Benchmarks
Machine Learning Mastery's guide explores core strategies for LLM inference optimization aimed at making language models faster, cheaper, and more reliable.

- Machine Learning Mastery published 'The Roadmap to Mastering LLM Inference Optimization' on September 21, 2026.
- The guide highlights methods to make language models faster, cheaper, and more reliable during inference.
- According to the Hugging Face Blog, LFM2.5-DSpark achieves up to 3.2x faster inference.
- Detailed framework recommendations and granular benchmarks remain subject to empirical verification across different setups.
Introduction
On September 21, 2026, educational technology publisher Machine Learning Mastery released an instructional guide titled 'The Roadmap to Mastering LLM Inference Optimization'. The resource outlines strategies and operational principles designed to improve the execution efficiency of large language models during inference.
As artificial intelligence deployments scale, optimizing inference performance has become a critical objective for engineering teams. The guide published by Machine Learning Mastery focuses on how targeted optimization techniques enable developers to improve core deployment metrics.
Prerequisites
Before deploying optimization techniques in production, developers must understand the core objectives of inference efficiency. The techniques outlined in Machine Learning Mastery's guide target three primary performance outcomes: improving execution speed, achieving cost-efficiency, and maintaining output reliability.
Establishing baseline metrics across these three areas helps teams identify operational bottlenecks. Essential targets include:
- Model speed: Accelerating token generation to reduce response latency.
- Cost-efficiency: Reducing compute resource overhead to make hosting language models cheaper.
- System reliability: Ensuring consistent output quality and operational stability under load.
Step-by-Step
While exact configuration workflows vary across hardware architectures and software stacks, industry benchmarks highlight the potential impact of optimized inference setups. For example, reporting from the Hugging Face Blog demonstrates that LFM2.5-DSpark can deliver up to 3.2x faster inference compared to standard setups.
A structured approach to implementing inference optimization involves evaluating baseline metrics and adopting high-efficiency pipelines:
- Establish baseline measures for latency, resource usage, and per-query compute costs.
- Implement optimized model execution frameworks such as LFM2.5-DSpark.
- Measure performance changes against baseline figures to ensure speed gains maintain reliability.
Reports indicate that specific performance gains and technical recommendations across custom setups require detailed technical verification prior to production rollout.
Best Practices
Adopting best practices in inference optimization requires balancing raw execution speed against operational costs and system stability. Core LLM inference optimization techniques aim to make language models faster, cheaper, and more reliable overall.
Documented developments show measurable advantages when applying modern optimization setups. As highlighted by the Hugging Face Blog, achieving up to 3.2x faster inference using tools like LFM2.5-DSpark illustrates how model execution performance can be enhanced without sacrificing operational stability.
Common Mistakes
A common mistake in inference optimization is deploying unverified optimizations without measuring their impact on overall reliability and cost. Optimization strategies must deliver clear efficiency gains without compromising the model's reliability.
Another frequent pitfall is assuming benchmark gains apply uniformly across all hardware environments. Although the Hugging Face Blog reports up to 3.2x faster inference with LFM2.5-DSpark, specific technical recommendations and performance gains require empirical verification on target hardware before full-scale deployment.
Conclusion
Machine Learning Mastery's September 21, 2026 guide emphasizes the growing necessity of mastering LLM inference optimization. By leveraging setups capable of delivering up to 3.2x faster inference, as demonstrated by LFM2.5-DSpark on the Hugging Face Blog, teams can build faster, cheaper, and more reliable language model applications.
Frequently Asked Questions
Related Stories

Hcompany Introduces Holo4 to Power Generalist Computer-Use Agents
Hcompany has published details on Hugging Face introducing Holo4, a model designed to power generalist computer-use agents across desktop and web environments.
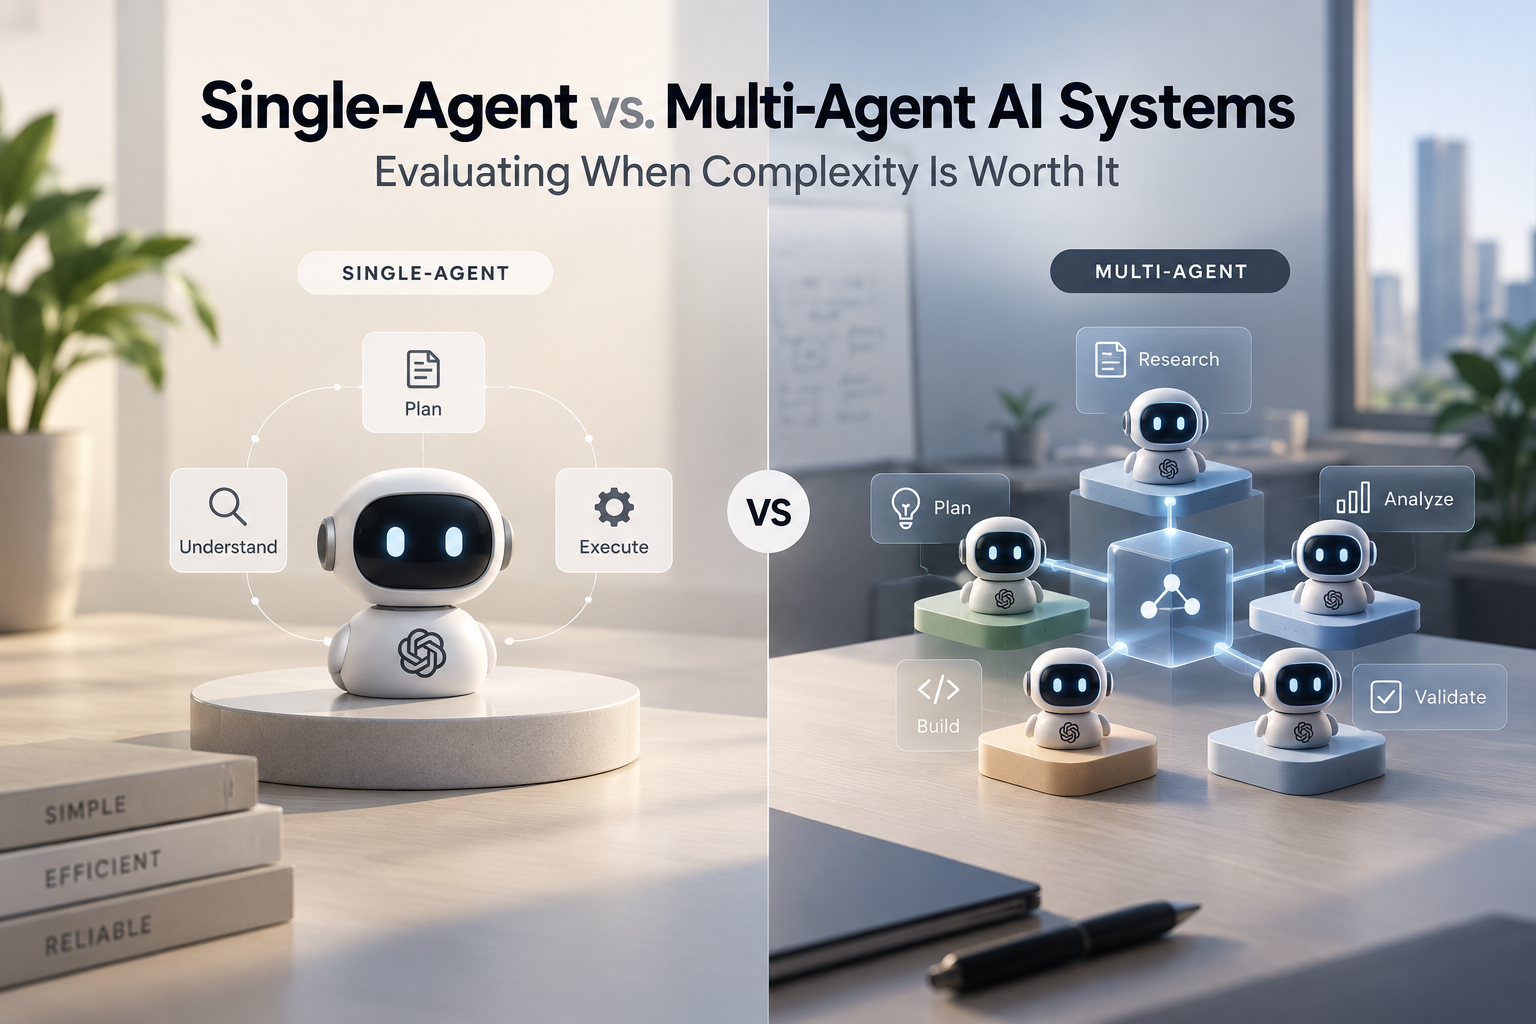
Single-Agent vs. Multi-Agent AI Systems: Evaluating When Complexity Is Worth It
Machine Learning Mastery has published an architectural guide comparing single-agent and multi-agent AI system designs, providing software architects with decision criteria for complex problem sets.
Nvidia Acquires Hugging Face for $13 Billion: A New Era for Open-Source AI
Nvidia's acquisition of Hugging Face signifies a pivotal moment in the AI landscape, promising to maintain the open-source ethos of the platform.